NASSCOM Futureskills Prime Certified Advanced Data Science with Gen AI including Free Internship & 100% Placement Assistance
Transform Your Career with Data Science + Generative AI
This advanced NASSCOM FutureSkills Prime Certified Data Science course in Hyderabad guarantees career transformation. Here’s a one-time opportunity to learn with the best Data Science training in Hyderabad, with an additional Professional Certification from TIH at IIT Bombay available to eligible learners. Gain knowledge of data analytics, tools, and operations for data science certification and meet the massive demand for these skills.
Here you will learn to read, analyze, clean, engineer, and present data in a way that promotes the growth of your business. To drive data and extract significant results, this Data Science course can help you progress in leaps and bounds. This NASSCOM FutureSkills Prime Certified Data Science training, backed by the TIH at IIT Bombay certification, will accelerate your career as it covers relevant topics and pushes you to work on real-time scenarios.
Artificial Intelligence and Machine Learning , Agentic AI in Data Science technology are constantly revolutionizing the industry by innovating and solving complex business problems.
Our principle of holistic development lies in the strong bedrock that believes in the amalgamation of theoretical knowledge along with practical training.
PREREQUISITE: The candidate must be pursuing a Bachelor’s Degree.
Previous coding experience is an added benefit.
Data Science Course Curriculum
NASSCOM FutureSkills Prime Certified | TIH at IIT Bombay
Module 1 : Python Programming
Introduction to Python Programming
- What is Python programming language?
- Why is Python programming language required for Data Science?
- What is Anaconda?
- Installation of Anaconda
- Understanding Jupyter Notebook
- Basic commands in Jupyter Notebook
- Understanding Python Syntax
- Data Types in Python broadly discussed
Literals, Keywords and Data Types
- What is an Identifier?
- Rules for Identifier Naming
- Inbuilt Keywords
- Variables and Data Types
- print() and input()
Python Operators
- Arithmetic Operators
- Assignment Operators
- Comparison Operators (Relational)
- Logical Operators
- Identity Operators
Conditional Statements
- What are Conditional Statements?
- if Statement
- if else Syntax
- if elif else
- Nested if and if else
- elif Ladder
While Loops & While-Else
- What is a Loop?
- Why Loops are Used?
- while Loop Syntax
- Control Flow
- Solving Pattern Problems
Lists
- What is a List?
- How to Define a List?
- Accessing List Elements Using Indexing and Slicing
- Built-in Methods
- Basic Examples Using Lists to Print Elements at Even Index, etc.
Tuple & Set
- What is a Tuple?
- How to Create a Tuple?
- Accessing Tuple Elements Using Indexing and Slicing
- Differences Between Lists and Tuples
- What is a Set?
- How to Create a Set?
- Built-in Methods
- Set Operations
- Manipulating and Accessing Sets
Dictionary
- What is a Dictionary?
- How to Create a Dictionary?
- Adding, Modifying and Retrieving Values from a Dictionary
- Getting All Methods
- Built-in Methods
- Differences Between Sets and Dictionaries
- Mutable vs Immutable Data Types
Strings
- What is a String?
- Create a String
- Accessing a String Using Indexing and Slicing
- Built-in Methods
- format() Method
- User Input / Dynamic Entry
- Type Casting of Strings
For Loop, For-Else & Comprehension
- Introduction to for Loop, range(), enumerate()
- For-Else
- List Comprehension & Dictionary Comprehension
- Problem Solving with String Methods Using for Loops & Conditional Statements
- Using chr() and ord()
- Problem Solving with Lists and Dictionaries
- Comprehension
Functions
- What is a Function?
- Why Functions are Used?
- Terminologies Used in Functions
- How to Define a Function?
- How to Call a Function?
- Positional and Keyword Arguments
Higher Order Functions
- Functions With / Without Return Values
- Lambda Functions
- Map, Filter & Reduce
- Namespaces
- Modules and Packages
- Using Conditional Statements
- Using Loops
- Using Functions
Modules & Packages
- Modules and Packages
- Datetime
- Random
- math, os
- Creating Custom Modules
OOPS – Classes and Objects
- What is a Class?
- How to Create a Class?
- What are the Properties and Methods of a Class? What is an Object?
- How to Create an Object?
- How to Access the Properties and Methods of a Class Using an Object?
- What is a Constructor?
- Types of Variables, Types of Methods and Access Modifiers
Inheritance & Abstraction
- Inheritance
- Single Inheritance
- Multilevel Inheritance
- Multiple Inheritance
- Hierarchical Inheritance
- Hybrid Inheritance and MRO
- Abstraction
Polymorphism and Encapsulation
- Polymorphism
- Dynamically Typed or Duck Typing
- Operator, Method and Constructor Overloading
- Method and Constructor Overriding
- Encapsulation
- Setter and Getter
File Handling & Exception Handling
- What is a File?
- How to Create, Open and Close a File?
- Writing to a File
- Appending to a File
- Reading from a File
- Testing File Existence
- What is an Exception?
- Raising Exceptions
- try and finally
- Custom Exceptions
VS Code & Streamlit Deployment
- What is Streamlit?
- Components of Streamlit
- Creating an Application with Streamlit
- VS Code, Setting Environment
- Executing Programs in VS Code
Backend with FastAPI
- Client-Server Architecture
- Introduction to FastAPI
- Request Methods
- Hands-on FastAPI
- Application Building
- Integration of FastAPI with Streamlit
- Case Study
GenAI: Enhanced Coding Fundamentals
- Introduction to AI-Assisted Coding
- ChatGPT for Code Generation and Explanation
- AI-Assisted Debugging and Code Optimization
- Generating Python Solutions with ChatGPT
- Hands-on AI-Assisted Coding for Data Science Tasks
Module 2 : EDA with Applied Statistics
Introduction to EDA
- How is EDA different from Python programming?
- EDA vs Python with Case Study
- Types of Data (Numerical, Categorical)
- Types of Analysis (Non-Visual and Visual, Univariate and Bivariate, Descriptive, Inferential & Probabilistic)
Descriptive Statistics
- What and Why Statistics?
- Data and its Measures
- Measures of Central Tendency (Univariate Analysis)
- Measures of Dispersion (Univariate Analysis)
- Measures of Correlation (Bivariate Analysis)
Core NumPy Operations
- Generating Random Numbers – np.random.rand, np.random.randn, np.random.randint, np.random.uniform
- Indexing and Slicing of Arrays (1D & 2D)
- Indexing with Boolean Arrays
- Updating NumPy Array
- Insert, Append and Delete
- Array Shape Manipulations – reshape, ravel, flatten, transpose
- Problem Solving
Mathematical & Statistical Functions
- Iterating Over a 1D and 2D NumPy Array
- Iteration Using np.nditer()
- Python Operators on NumPy Array
- NumPy Maths – sqrt(), exp(), sin(), cos(), add(), subtract(), multiply(), divide(), dot(), @ Operator
- NumPy Statistics – sum(), min(), max(), mean(), median(), var(), std(), corrcoef()
Vectorization and Advanced NumPy Functions
- Array Manipulations – concatenate, vstack, hstack, column_stack, hsplit, vsplit
- Sorting the Data in an Array – sort, argsort
- Broadcasting Arrays
- NumPy where, any
Introduction to Pandas
- Introduction to Pandas
- Pandas Series
- Pandas DataFrame
- Difference Between Series and DataFrame
- Creating Series and DataFrames
Data Exploration and Understanding
- Loading Data from CSV and Excel Files
- Understanding the DataFrame Structure
- DataFrame Non-Indexing Attributes
- DataFrame Utility Methods
- DataFrame Iteration Methods
- Mathematical Functions on Whole DataFrame
- Getting Column Index / Label
- Changing Column Labels
- Selecting and Swapping Columns
- Adding New Columns / Dropping Existing Columns
- Vectorized Arithmetic Operations
- Data Type Conversions
- Math and Statistical Functions on Columns
GroupBy and Pivot on DataFrame
- Summarizing Data Using groupby()
- Multidimensional Aggregation Using pivot_table()
- Categorical Analysis Using crosstab
Working With Multiple Tables Using Joins (Merge Operation)
- Concatenation – Vertical and Horizontal Stacking
- Merging (merge) – Inner, Outer, Left and Right Joins
- Index-Based Merging
Handling Missing Values, String and Datetime Manipulations
- Types of Missing Data
- Identifying and Visualizing Missing Data
- Missing Value Imputation
- String Operations
- Working with Datetime
Advanced Data Transformations
- apply() and map()
- Window Functions – rolling(), expanding()
- Handling JSON Files
- JSON record_path Normalization
Univariate and Bivariate Statistical Analysis (Non-Visual)
- Measures of Shape
- Measure of Relationship
- Case Study – Descriptive Statistics
Introduction to Data Visualization
- Understanding Visualization
- Basic Structure of a Plot – Figure, Axis, Title, Legends, Ticks, Labels, Subplots
- Creating Basic Plots with Raw Data
- Customizing the Plots – Colormaps, Axis Limits, Markers, Linestyles, Colors
Univariate Analysis with Matplotlib / Seaborn
- Univariate Plots for Numeric Data – Histogram, KDE, Boxplot, Violinplot
- Univariate Plots for Categorical Data – Barplot, Countplot
Bivariate and Multivariate Analysis with Matplotlib / Seaborn
- Plots Between Numerical Variables – Scatterplot, Heatmap, Lineplot
- Plots Between Categorical Variables – KDE Plot, Boxplot, Histogram, Boxenplot, Violinplot
- Plots Between a Numeric and a Categorical Variable – Countplot, Stacked Barplot
- Plots for Multivariate Analysis – Pairplot, Heatmap
Interactive Data Visualization with Plotly
- Interactive Plots for Numeric Data – Histogram, Boxplot, Violinplot, Density Plot
- Interactive Plots for Categorical Data – Bar Chart, Grouped Bar Chart, Pie Chart, Funnel Chart
- Interactive Plots for Bivariate Analysis – Scatterplot, Line Chart, Bubble Chart, Area Chart
- Interactive Plots for Multivariate Analysis – Heatmap, Scatter Matrix, Parallel Coordinates
- Advanced Plotly Visualizations – Subplots, Animations, Hover Interactions, Filters
Introduction to Probability
- Random Experiment
- Sample Space
- Event
- Axioms of Probability
- Basic Probability Examples
Frequency Tables
- Introduction to Frequency Tables
- Joint Probability
- Marginal Probability
- Conditional Probability
Introduction to Data Distributions, Discrete Data Distributions
- What is a Data Distribution?
- Why Study Data Distribution?
- Key Characteristics
- Types of Distributions
- Introduction to SciPy Library
- Bernoulli, Binomial, and Poisson
Continuous Data Distribution
- Uniform, Normal
- Exponential
- LogNormal
- Pareto Distribution
- 68-95-99.7% Rule
- Verify the Distribution Using QQ Plot
Feature Engineering
- Feature Scaling – Normalization and Standardization
- Data Transformation
- Log Transformation and Box-Cox
Introduction to Inferential Statistics
- Inferential Statistics
- Population vs Sample
- Why Inferential Statistics?
- Sampling Techniques – Convenience Sampling, Systematic Sampling, Simple Random Sampling, Stratified Sampling, Cluster Sampling
- Sampling in Pandas DataFrame
Central Limit Theorem and Point Estimate
- Performing Estimations
- Point Estimate Using Single Sample
- Central Limit Theorem
- Point Estimate Using Multiple Samples
Confidence Interval Estimate
- Confidence Interval Estimates Using 1 Sample (Population Std Known and Unknown)
- Confidence Level
- Significance Level
- Critical Value – Z-Score and T-Score
Hypothesis Testing and Advanced Statistical Tests
- What is Hypothesis Testing?
- What is p-value?
- Important Hypothesis Tests
- Type I and Type II Errors
- Parametric and Non-Parametric Tests – Chi-Square Test, ANOVA
Simplifying Statistical Analysis with AI Tools
- Introduction to AI-Assisted Statistical Analysis – Role of GenAI in Statistics
- AI-Assisted Descriptive Statistics – Mean, Median, Mode, Variance and Standard Deviation
- AI-Assisted Statistical Analysis – Correlation, Distribution and Hypothesis Testing
- Interpreting Statistical Results with GenAI – Insights and Explanations
- Hands-on with AI Tools – Statistical Analysis and Interpretation
Regular Expressions
- Pattern Matching Basics
- Email, Phone Number & URL Extraction
- Text Cleaning & Data Validation
- Removing Special Characters
- Regex with Python (re module)
Ethical Web Scraping
- Requests Library
- BeautifulSoup
- HTML Parsing
- CSS Selectors & Inspect Element
- Extracting Tables, Text & Links
- Pagination Handling
Data Cleaning & Preprocessing
- Handling Missing Values
- Removing Duplicates
- String Cleaning
- Formatting & Standardization
- Data Transformation Using Pandas
Exploratory Data Analysis (EDA)
- Data Understanding & Profiling
- Statistical Summary
- Data Visualization Using Matplotlib & Seaborn
- Correlation & Trend Analysis
- Business Insights Generation
Project on EDA
- Collect Real-Time Data from Websites Ethically
- Clean and Preprocess Raw Datasets
- Apply Regex for Data Extraction & Validation
- Perform EDA and Generate Insights
- Build Industry-Oriented Projects
GenAI: Powered Data Wrangling with PandasAI
- Introduction to Data Wrangling – Data Cleaning, Transformation, Integration
- Introduction to PandasAI – AI-Assisted Data Manipulation
- AI-Powered Data Cleaning – Missing Values, Duplicates, Data Types
- AI-Assisted Data Transformation – Filtering, Sorting, Aggregation
- Natural Language Data Analysis – Querying and Exploring Data with PandasAI
Module 3 : Database (MySQL)
Introduction to SQL
- Data
- What is Database?
- DBMS
- RDBMS
- SQL vs MySQL
- SQL vs NoSQL
- CRUD Operations
- Pandas vs SQL
- Client-Server Architecture
- Workbench Introduction
SQL Fundamentals
- Types of SQL Commands
- Data Types
- Constraints (PRIMARY KEY / AUTO_INCREMENT, NOT NULL, UNIQUE, DEFAULT, CHECK)
- Creating Tables with Constraints
- DDL (CREATE, ALTER, DROP, TRUNCATE)
- DML (INSERT, UPDATE, DELETE)
Multiple Tables
- Multiple Tables – Primary Key, Composite Key, Foreign Key
- Types of Relationships in SQL
- ER Diagram
- Case Study: On Relational Database
Data Exploration and Data Filtering (DQL and Operators)
- SELECT (Retrieve)
- Data Exploration – Selecting Columns; Performing LIMIT, DISTINCT, Aggregation Values, Indexing and Slicing Using OFFSET
- Data Filtering – Filtering Data Based on Conditions Using Operators (LIKE, REGEXP, BETWEEN)
- GROUP BY (Aggregate Functions)
- HAVING (Correlating with get_group in Pandas)
- ORDER BY
- CASE
- Order of Execution
- Case Study: A Case Study of Clauses
Joins, Unions and Subquery
- Types of Joins – INNER JOIN, OUTER JOIN (LEFT, RIGHT), CROSS JOIN, SELF JOIN
- Set Operations – UNION, UNION ALL
- Subquery – Scalar Subquery, Multiple Subquery, Correlated Subquery
Temporary Tables
- Derived Table
- CTE
- Inbuilt Functions
- Window Functions
- Case Study: A Case Study of Temporary Tables
SQL Database Objects
- Views
- Stored Procedures
- Functions
Advanced Topics
- Transaction Control Language – ACID Properties, COMMIT, ROLLBACK, SAVEPOINT
- Triggers
- Type Conversion, Working with Date, Time & String Functions
- Connectivity of MySQL with Python (Pandas)
Project on MySQL
- Analyze Normalized Relational Databases and ER Diagrams Based on Real-World Business Requirements
- Import and Manage CSV Datasets in SQL Databases
- Write SQL Queries Using Filters, Aggregations, Sorting and Joins
- Develop Advanced SQL Solutions Using CTEs, Views, Stored Procedures and Window Functions
- Solve Domain-Specific Business Problems and Generate Actionable Insights
GenAI Powered SQL: Query Generation & Optimization
- Introduction to AI-Powered SQL – AI-Assisted SQL Concepts and Workflows
- AI-Assisted Query Generation – Natural Language to SQL
- AI-Assisted Query Optimization – Query Performance and Optimization
- SQL Debugging with GenAI – Error Identification and Correction
- Hands-on with AI-Powered SQL – Query Generation and Optimization
Module 4: Reporting Tool (Power Bi)
Excel Essentials for Data Analysis
- Introduction to Excel for Data Analysis
- Data Exploration Using Excel Functions
- Data Cleaning and Formatting in Excel
- Sorting, Filtering and Data Validation
- Conditional Formatting and Data Highlighting
- Lookup Functions: VLOOKUP, XLOOKUP and INDEX-MATCH
- Pivot Tables and Pivot Charts for Data Analysis
- Advanced Excel Functions for Data Analysis
- Case Study: Dashboarding in Excel
Introduction to Power BI
- What is Business Intelligence?
- Power BI Introduction
- Quadrant Report
- Comparison with Other BI Tools
- Power BI Desktop Overview
- Power BI Workflow
Data Import and Data Visualizations
- Data Import Options in Power BI
- Import from Web (Hands-on)
- Why Visualization?
- Visualization Types
- Categorical Data Visualization
- Trend Data Visualization
Power Query
- Power Query Introduction
- Data Transformation – Its Benefits
- Introducing Ribbons
- Queries Panel
- M Language Briefing
- Power BI Data Types
- Changing Data Types of Columns
- Filtering
- Inbuilt Column Transformations
- Inbuilt Row Transformations
- Combine Queries
- Merge Queries
Power Pivot and Introduction to DAX
- Power Pivot
- Introduction to Data Modeling
- Relationship and Cardinality
- Relationship View
- Calculated Columns vs Measures
- DAX Introduction and Syntax
Data Analysis Expressions
- DAX Logical Functions
- DAX Text Functions
- DAX Math and Statistical Functions
- DAX Aggregation Functions
- DAX Filter Functions
- DAX Time Intelligence Functions
- Creating a Date Dimension Table
- Related Aspects with Tables
Login, Publish to Web and RLS
- Power BI Services
- Dashboard Creation
- Web Content, Image, Text Box
- Dashboard Formatting
- Sharing Your Dashboard
- RLS Introduction
Miscellaneous Topics
- Visual Interactions
- Drill Through
- Drill Down
- Conditional Formatting
- Creating Buttons in Power BI Reports
- Creating Python Script Visuals
Project on Power BI
- Understand Business Problems and Define Reporting Objectives
- Load Data from Multiple Sources into Power BI
- Clean and Transform Data Using Power Query
- Build Data Models and Establish Relationships
- Create DAX Measures and Calculated Columns
- Design Interactive Dashboards and Reports
- Generate Insights and Business Recommendations Across Multiple Industry Domains
GenAI: Enhanced Presentations with ChatGPT
- Introduction to AI-Enhanced Presentations – Role of GenAI in Data Storytelling
- AI-Assisted Content Creation – Insights, Summaries and Key Takeaways
- AI-Assisted Presentation Design – Structure, Visuals and Slide Content
- Data Storytelling with ChatGPT – Converting Analysis into Narratives
- Hands-on with ChatGPT – Creating Data-Driven Presentations
Module 5 : Machine Learning Foundations
Machine Learning Foundations
- Why Machine Learning?
- AI vs ML vs Deep Learning
- Supervised vs Unsupervised Learning
- Regression vs Classification
- Machine Learning Workflow / Lifecycle
Problem Definition & Objective
- Business Problem Statement
- Defining ML Objectives
- Identifying Features and Target
- Identifying Regression or Classification Tasks
Feature Engineering
- Feature Transformation
- Feature Selection
- Feature Importance
Train-Test Split
- Training and Testing Data
- Importance of Data Splitting
- Avoiding Data Leakage
Numerical Data Preprocessing
- Numerical Feature Preprocessing
- Feature Scaling
- Types of Feature Scaling
- Standardization, Normalization
Categorical Data Preprocessing
- Categorical Feature Preprocessing
- Encoding Techniques
- One-Hot Encoding
- Ordinal Encoding
Supervised Learning – Classification Algorithms
- Introduction to Classification
- K-Nearest Neighbors (KNN)
- Logistic Regression
- Naive Bayes
- Decision Tree
Supervised Learning – Regression Algorithms
- Introduction to Regression
- Linear Regression
- KNN for Regression
- Decision Tree for Regression
Data Collection
- Data Sources
- Data Collection Methods
- Loading and Understanding Datasets
Exploratory Data Analysis (EDA)
- Univariate, Bivariate and Multivariate Analysis
- Visual and Non-Visual Statistics
- Understanding Data Distributions and Relationships
Data Quality Assessment
- Identifying Duplicates
- Handling Null and Missing Values
- Detecting Outliers
- Data Type and Consistency Checks
Model Building with Scikit-learn
- Model Training and Prediction
- Applying Preprocessing and Models
- Building ML Pipelines
- Hands-on Model Implementation
Regression Evaluation Metrics
- Mean Absolute Error (MAE)
- Mean Squared Error (MSE)
- Root Mean Squared Error (RMSE)
- R² Score
- Adjusted R² Score
Classification Evaluation Metrics
- Confusion Matrix
- Accuracy, Precision and Recall
- F1 Score
- Classification Report
Hyperparameter Tuning
- Parameters vs Hyperparameters
- Introduction to Cross-Validation
- GridSearchCV
- RandomizedSearchCV
- Model Selection and Tuning
GenAI: Enhanced Machine Learning Case Study
- Problem Definition & Data Understanding – Problem Statement, Objectives and AI-Assisted Data Exploration
- EDA & Data Preparation – AI-Assisted EDA, Data Cleaning and Feature Engineering
- Model Building & Evaluation – AI-Assisted Model Selection, Training and Evaluation
- Model Optimization & Interpretation – AI-Assisted Hyperparameter Tuning and Result Interpretation
- Business Insights & Deployment – AI-Assisted Insights and Reporting
Module 6 : GenAI Fundamentals for Data Analysts
GenAI Fundamentals for Data Analysts
- Introduction to Generative AI
- Generative AI vs Traditional AI
- Applications of GenAI in Data Analytics
- Overview of GenAI Tools – ChatGPT, Gemini, Gamma
Understanding LLMs
- What are Large Language Models?
- Context, Prompts and Responses
- Data Relevance and Hallucinations
- Limitations of LLMs
Prompt Engineering Essentials for Data Analytics
- Introduction to Prompt Engineering
- Effective Prompt Structure
- Context, Role and Constraints
- Iterative Prompting and Refinement
Prompting for Data Tasks
- Prompts for Data Understanding
- Prompts for Data Cleaning and EDA
- Prompts for Data Interpretation
GenAI for Data Cleaning & EDA
- AI-Assisted Data Understanding
- Identifying Missing Values, Duplicates and Outliers
GenAI for Code & SQL
- AI-Assisted Python Code Generation
- Code Explanation and Debugging
- AI-Assisted SQL Query Generation
- Query Optimization and Validation
GenAI for Analytics Reporting
- Converting Analysis into Insights
- AI-Assisted Report, PPT and PDF Generation Using ChatGPT
- Data Storytelling with GenAI
- Creating Presentations with Gamma
Multimodal GenAI for Data Analytics
- Understanding Text, Images and Tables with GenAI
- Extracting Information from Documents and Images
- Image and Chart Interpretation
- Multimodal Analysis with ChatGPT and Gemini
Automating Data Analytics Workflows
- Introduction to AI-Assisted Automation
- Automating Repetitive Analytics Tasks
- Connecting Data and GenAI Tools
- Workflow Design with GenAI
No-Code AI Automation with n8n
- Introduction to n8n
- Connecting AI Models with Data Sources
- Building AI-Assisted Analytics Workflows
- Automating Reports and Notifications
Responsible GenAI for Data Analytics
- AI Limitations and Hallucinations
- Data Privacy and Security
- Bias and Responsible AI Usage
- Human Validation and Oversight
GenAI: Enhanced Data Analytics Case Study
- Problem Definition and Data Understanding
- AI-Assisted EDA and Data Preparation
- AI-Assisted Analysis, Reporting and Visualization
- Workflow Automation Using GenAI Tools
- Validating AI Outputs and Generating Business Insights
GenAI Tools & Future of Data Analytics
- Comparing GenAI Tools for Data Tasks
- Selecting the Right Tool for the Task
- Building Personal GenAI Workflows
- Staying Current with Emerging GenAI Tools
Ethics, Responsibility & Staying Current with GenAI
- AI Ethics, Bias and Responsible AI Usage
- Data Privacy, Security and Intellectual Property
- Hallucinations, Human Validation and AI Reliability
- Staying Current with Emerging GenAI Tools and Technologies
Synthetic Data & Image Generation
- Introduction to Synthetic Data Generation
- Generating Synthetic Data for Testing and Analysis
- Introduction to AI-Based Image Generation and Use Cases
Module 7 : Data analytics Projects & Capstone
- Retail Sales Analysis
- Student Performance Analysis
- People Ops Analytics
- HR Analytics – Employee Attrition & Performance Analysis
- Pricing Strategy Analysis
- AI-Augmented Business Intelligence
Module 8: Applied Machine Learning
Applied Machine Learning
Text Preprocessing
- Text Data – Introduction to NLP
- Why Text Data is Hard to Work With
- Cleaning Text Data
- Tokenisation
- Stop Words
- Lemmatization
- Stemming
Text Transformation
- Bag of Words
- Term Frequency-Inverse Document Frequency
- Spam-Ham Detection
Working with Image Data
- Image Data – Understanding Images
- RGB Channels
- Images as 3D NumPy Arrays
- Image Case Study
Mathematical Foundations
- Introduction and Why Linear Algebra
- Fundamentals of Vectors and Matrices
- Unit Vector
- Matrix Operations
- Dot Product of Vectors
- Angle Between Two Vectors
- Projection of a Vector onto Another Vector
- Length of Projection
- Distances and Dot Products
KNN for Classification & Regression
- Intuition Behind KNN
- Developing the Algorithm for KNN
- Solving Classification Problems with KNN
- Solving Regression Problems with KNN
- Code Implementation for KNN
- Hyperparameter Tuning
Naive Bayes Derivation, Solving an Example with NB
- Derivation of Naive Bayes Algorithm
- Solving an Example
- Code Implementation, NB Example
Decision Tree (DT) Algorithm
- Introduction to Rule-Based Approach to Solve Classification and Regression Problems
- Building Decision Trees
- ID3, C4.5, C5.0 Algorithms to Build Decision Trees
- Concept of Entropy, Information Gain and Gini Impurity
- Python Code Sample
DT for Classification and Regression
- Working of DT with Numerical Input Data
- DT for Regression
- Reduction of Variance
- Solving an Example with DT
Equation of Line and Linear Regression, Multiple Linear Regression
- Understanding Equation of a Line and Hyperplane
- Intuition Behind Linear Regression
- Building a Cost Function for Regression and Classification Problem
- Mathematical Formulation of Linear Regression
- Calculating the Errors
- Python Implementation, Simple Linear Regression vs Multiple Linear Regression
- Issues with Multiple Linear Regression
- Python Implementation
- Issue of Multicollinearity
- Detecting Multicollinearity with VIF
Linear Regression Edge Cases
- Linear Regression with Polynomial Features
- Assumptions of Linear Regression
- Hands-on
Gradient Descent
- Understanding Differentiation of a Function
- Slope of Tangent
- Computing Derivative
- Computing Maxima and Minima
- Iterative Algorithm to Solve the Problem of Maxima and Minima
- Update Function of Gradient Descent
Logistic Regression
- Geometric Intuition Behind Logistic Regression
- Mathematical Formulation of Logistic Regression
- Signed Distance Formulation
- Sigmoid Function
- Numerical Instability Issue
- Assumptions of Logistic Regression
- Code Sample
Support Vector Machines
- Intro to SVM
- Solving Classification Problem Using SVM
- Logistic Regression vs SVC
- Margin Maximization
- Hard Margin Support Vector Classifier, Soft Margin Support Vector Classifier
- How Kernel Trick Works?
- Pros and Cons of SVC
Parallel Ensembles
- Introducing Model Ensembles
- Voting Ensembles
- Stacking
- Bagging – Random Forest Case Study
Sequential Ensembles
- Cascading
- Boosting
- AdaBoost
- GBDT
- XGBoost Case Study
Feature Engineering – Transformation, Feature Engineering – Selection
- Revision on Feature Transformation
- Feature Selection Introduction
- Variance Thresholding, Variance Inflation Factor
- Recursive Feature Elimination
- Lasso Regularization
- Decision Tree for Feature Importance
- Implementation Using Python
Introduction to Unsupervised Learning and K-Means, K-Means++
- Understanding Unsupervised Learning
- Clustering
- Applications of Clustering
- K-Means Algorithm
- Python Code Sample, K-Means++ Initialisation
Hierarchical Clustering, Customer Segmentation
- Intro to Hierarchical Clustering
- Merging
- Linkage – Single, Centroid, Complete
- Dendrogram
- Cut Tree
- Solving Customer Segmentation Using Clustering
PCA and Use Case
- Introduction to Dimensionality Reduction
- Introduction to Principal Component Analysis
- Eigenvalues and Eigenvectors
- Orthogonality
- Transforming Eigenvalues
- Proportion of Variance Explained in PCA
- Code Implementation
Time Series Forecasting
- Introduction to Time Series Data
- Components of Time Series – Trend, Seasonality & Residuals
- Time Series Analysis and Visualization
- Time-Based Train-Test Split
- Introduction to Forecasting
- Forecasting with Machine Learning
- Model Evaluation for Time Series Forecasting
- Hands-on Time Series Forecasting Case Study
AutoML & GenAI-Assisted Modeling
- Introduction to AutoML
- Automated Data Preprocessing, Feature Engineering & Model Selection
- Introduction to GenAI-Assisted Machine Learning
- AI-Assisted Model Selection, Code Generation & Debugging
- AI-Assisted Model Interpretation and Insights
- Hands-on AutoML & GenAI-Assisted Modeling
Exclusively for ✳ TIH at IIT Bombay
Explainable AI: Model Interpretation with LIME & SHAP
- Introduction to Explainable AI (XAI) and Model Interpretability
- Importance of Model Interpretation in Machine Learning
- Global vs Local Model Interpretability
- Model Interpretation Using SHAP (SHapley Additive exPlanations)
- Model Interpretation Using LIME (Local Interpretable Model-Agnostic Explanations)
- Feature Importance and Prediction-Level Explanations
- Interpreting and Communicating Model Insights
- Hands-on LIME & SHAP Model Interpretation Case Study
Exclusively for ✳ TIH at IIT Bombay
Project on Machine Learning
- Understand Business Problems and Define Clear Machine Learning Objectives
- Collect and Integrate Datasets from Multiple Sources or Publicly Available Repositories
- Perform Data Cleaning, Preprocessing, and Feature Engineering
- Conduct Exploratory Data Analysis (EDA) to Identify Trends, Patterns, and Relationships
- Prepare Training, Validation, and Testing Datasets Using Appropriate Data-Splitting Strategies
- Build and Train Supervised and Unsupervised Machine Learning Models
- Evaluate Model Performance Using Appropriate Evaluation Metrics
- Optimize Models Using Hyperparameter Tuning and Cross-Validation
- Apply LIME and SHAP for Model Interpretability and Explainable AI
- Interpret Model Predictions and Translate Findings into Actionable Business Insights
- Implement MLOps Practices Using MLflow for Experiment Tracking and Model Management
- Track Model Parameters, Metrics, Versions, and Training Workflows
- Deploy Machine Learning Applications Using Streamlit
- Develop End-to-End ML Pipelines for Practical and Scalable Real-World Applications
Module 9 : Deep Learning and Artificial Neural Networks
Introduction to Deep Learning and Artificial Neural Networks
- Understanding Biological Neuron
- Analogy Between Biological and Artificial Neuron
- Single Layer Perceptron Model
- Understanding Weights, Bias and Activation
Perceptron Model
- Perceptron Learning Rule
- Artificial Neuron
- MLP / FCNN / ANN Model
- Nomenclature of ANN
Training Neural Network
- Forward Pass with Formulation
- Backward Pass (Without Formulation)
- Understanding Backpropagation Algorithm (Using AutoGrad Methods like GradientTape in TensorFlow)
ANN Model Building
- Classification Model Building Using TensorFlow/Keras
- Regression Model Building Using TensorFlow/Keras (As an Assignment)
- Evaluating Model
Neuron Activation Function and Output Functions
- Linear Activation
- Sigmoid Function
- Tanh Function
- ReLU Function (LeakyReLU, Parametric ReLU)
- Softmax Function
Optimizers
- Gradient Descent
- Mini-Batch Gradient Descent
- Momentum-Based Gradient Descent
- Adaptive Gradient Descent
- Adam
- RMSProp
Overfitting in ANN
- L1 and L2 Regularization
- Dropout Regularizer
- Early Stopping
- Batch Normalization
Hyperparameter Tuning in ANN
- Introduction to Optuna
- Creating a Study in Optuna
- Finding Hyperparameters Using Optuna
- Hyperparameter Importance Using Optuna
Project on ANN
- Understand Business Problems and Define Machine Learning Objectives
- Collect Datasets from Multiple Sources or Work with Publicly Available Datasets
- Perform Data Cleaning and Preprocessing
- Split Data into Training, Validation, and Testing Datasets
- Build Supervised ANN Models
- Evaluate Model Performance Using Appropriate Metrics
- Optimize Models Using Hyperparameter Tuning
- Track Model Metrics, Parameters, Versions and Training Workflows
- Interpret Model Outputs and Generate Actionable Business Insights
- Deploy Machine Learning Applications Using Streamlit
- Create End-to-End ML Pipelines for Scalable Real-World Applications
Module 10: Applied NLP with Transformers
Applied NLP with Transformers
Introduction to Text and its Preprocessing with NLTK or SpaCy
- Introduction to NLP
- Text Preprocessing Steps
- BOW, TF-IDF
- Coding for BOW and TF-IDF Using NLTK/SpaCy
Word Embeddings – Word2Vec
- Word2Vec
- Autoencoders
- How Word2Vec Algorithm Works (CBOW, Skip-gram)
Case Study – Text Classification
- Text Data Classification Case Study
Sequence Modelling with RNN
- Introduction to RNN
- Training of RNN
- Types of RNN
- Text Classification
LSTM, GRU
- Limitations of RNN
- Idea of LSTM, GRU
- POS Tagging
Self-Attention and Transformers
Seq2Seq Architecture
- Attention Mechanism
- Implementing Attention Layers
- Hands-on: RNN/LSTM + Attention
- Case Study-2: Case Study Machine Translation
Transformer Architecture
- Positional Encoding
- Self and Multi-Head Attention
- Masked Multi-Head Attention
- GPT with Autoregressive Language Modelling
- BERT with Auto-Encoding Language Modelling
Hugging Face API
- Introduction to Hugging Face
- Hugging Face Embeddings
- Case Study: Sentiment Analysis, Named Entity Recognition, Parts of Speech Tagging, Question & Answering
NLP Tasks Using Auto Classes
- Auto Classes – Config, Tokenization and Models
Text Generation & Question Answering
- Text Summarization
- Text Translation
Evaluation Metrics
- Introduction to Evaluation Metrics
- BLEU, ROUGE
- METEOR, Perplexity
Hugging Face for Image and Audio Data
- Image Classification
- Image Detection
- Audio Classification
Project on Natural Language Processing (NLP)
- Understand real-world text analytics problems and define NLP objectives.
- Collect textual datasets from multiple sources or use publicly available datasets.
- Perform text cleaning, tokenization, stemming, and lemmatization.
- Convert text into numerical representations using TF-IDF, Word Embeddings, and basic transformer pipelines.
- Build NLP models for tasks such as Sentiment Analysis, Text Classification, Spam Detection, and Chatbots.
- Train and evaluate NLP models using appropriate performance metrics.
- Extract insights from unstructured textual data.
- Deploy NLP applications using Streamlit.
- Build scalable NLP solutions for real-world business use cases.
Module 11: Advanced Generative AI and Agentic AI
Advanced Generative AI and Agentic AI
Introduction to LangChain
- Why LangChain?
- Import Chat Models
- Integrating with OpenAI/Gemini/Groq API
- LCEL Chain
Components of a Chain
- Prompt Template
- Chat Prompt Template
- System Message, Human Message & AI Messages
LCEL Chain
- Output Parser – StrOutputParser, PydanticParser
- Build a Basic Chatbot
Runnables
- RunnablePassthrough
- RunnableParallel
- Runnable
- Case Study
Conversation Memory
- Adding Memory to LangChain Applications
- Context Window Optimization
- Conversation Summarization Techniques
Monitoring and Observability
- Introduction to Monitoring and Observability
- Observability Tools
- Tracing Implementation
RAG Fundamentals
- What is RAG? and Why RAG?
- Document Loaders (PDF, Web, CSV)
- Text Splitters & Chunking
Embeddings and Vector Database
- Introduction to Vector Databases
- Working with Vector Databases – FAISS, Pinecone, Weaviate
- Storing, Indexing and Retrieving Vector Embeddings
- Vector Stores
- Vector Embeddings
- Retrieval Chain
Hybrid RAG
- Keyword, Semantic and Hybrid Search
- Re-ranking
- Embedding Models & Similarity Measures
- Semantic Search Using Vector Embeddings
- Metadata Filtering for Context-Aware Retrieval
- Combining Metadata Filtering with Hybrid Search
Exclusively for ✳ TIH at IIT Bombay
RAG Evaluation
- RAGAS Evaluation
- LLM-as-a-Judge
- End-to-End RAG Pipeline Architecture
- Building Production-Ready RAG Applications
- RAG with Multiple Data Sources and Documents
Exclusively for ✳ TIH at IIT Bombay
Tool Calling & Agents
- ReAct Loop
- Build a ReAct Agent Using CreateAgent
- Add Custom Tools (like Search and Wikipedia)
- Response Formatting
- Error Handling
- Memory with Checkpointer
- PII Middleware
- Tool Retry and Model Retry
Monitoring and Observability (MCP)
- MCP Client-Server Architecture
- Transport Protocol – stdio and HTTP
- JSON-RPC Protocol
- Creating MCP Host with MCP Client in LangChain
Introduction to LangGraph
- LangChain vs LangGraph
- What is State?
- State Schema – TypedDict
Building Workflows with LangGraph
- Building a Graph
- StateGraph – Adding Nodes and Edges
- Sequential, Parallel and Conditional Workflows
Conversational Chatbot with Memory and Tool
- Adding Memory to Graph
- InMemorySaver
- Add Tools to Chatbot
Streaming and Human in the Loop
- Streaming and its Types
- Human in the Loop (HITL)
LangGraph Application Deployment
- LangGraph Agent Deployment
- Agent Chat UI
Fine-Tuning Transformers for NLP Tasks
- Trainer API, Training Arguments
- Sequence-to-Sequence vs Causal SFT
- Case Study – Text Summarization
PEFT with LoRA and QLoRA
- PEFT
- Low-Rank Adaptation (LoRA)
- Bitsandbytes Integration
- QLoRA
Building End-to-End AI Applications
- AI Application Architecture – From Idea to Implementation
- Integrating LLMs, RAG, Tools & APIs
- Building End-to-End AI Applications with Streamlit
- Testing, Validation & Deployment of AI Applications
Project on GenAI
- Understand real-world business problems and define Generative AI objectives.
- Collect datasets from multiple sources or use publicly available datasets.
- Preprocess and prepare textual data for Generative AI applications.
- Work with Large Language Models (LLMs) and prompt engineering techniques.
- Build applications – AI Chatbots, Document Q&A Systems, Text Summarization, & Content Generation tools.
- Integrate vector databases and embeddings for semantic search and retrieval.
- Implement Retrieval-Augmented Generation (RAG) pipelines.
- Evaluate Generative AI applications using relevant qualitative and quantitative metrics.
- Implement observability, tracing, and monitoring using tools such as Langfuse.
- Track prompts, responses, token usage, latency, and application performance.
- Deploy Generative AI applications using FastAPI and Streamlit.
- Build scalable end-to-end Generative AI solutions for real-world business use cases.
Project on Agentic AI
- Understand real-world business problems and define Agentic AI objectives.
- Design AI agents capable of reasoning, planning, and task execution.
- Integrate Large Language Models (LLMs) with external tools and APIs.
- Build multi-step workflows using agent frameworks and orchestration techniques.
- Develop AI agents for tasks such as Automation, Research Assistance, Data Analysis, & Workflow Management.
- Implement memory, context handling, and conversational capabilities in AI agents.
- Build Retrieval-Augmented Generation (RAG) and tool-calling pipelines for intelligent task execution.
- Evaluate agent performance based on accuracy, efficiency, and task completion.
- Implement observability, tracing, and monitoring using tools such as Langfuse.
- Monitor agent workflows, reasoning steps, latency, and tool usage.
- Deploy Agentic AI applications using FastAPI and Streamlit.
- Build scalable autonomous AI systems for real-world business applications.
Module 12: AI Deployment, LLMOps and Production Systems
AI Deployment, LLMOps & Production Systems
Building Production AI Applications
- FastAPI for AI Services
- Streamlit & Gradio
- API Design for AI Applications
- Authentication & Security
Exclusively for ✳ TIH at IIT Bombay
Containerization & Cloud
- Docker Essentials
- Deploying AI Applications
- Azure AI Services
- Azure AI Foundry
Exclusively for ✳ TIH at IIT Bombay
LLMOps
- Prompt Management
- Model Versioning
- Prompt Caching
- Cost Optimization
Exclusively for ✳ TIH at IIT Bombay
Evaluation & Monitoring
- Evaluating LLM Applications
- LangSmith
- RAGAS & DeepEval
- Hallucination Detection & Groundedness
Exclusively for ✳ TIH at IIT Bombay
Production Engineering
- Logging & Observability
- Tracing AI Applications
- Performance Optimization
- Scaling AI & Systems
- Enterprise AI Deployment
- Deploying Multi-Agent Applications
- CI/CD for AI
- Monitoring Production AI
Exclusively for ✳ TIH at IIT Bombay
Module 13: Computer Vision
Intro to Images and Image Preprocessing with OpenCV
- Introduction to an Image
- How Images are Formed and Stored in Machines
- Introduction to OpenCV – Read, Write and Save Images
- Converting to Different Color Spaces (RGB, BGR, HLS, HSV)
- Bitwise Operators on Images
Image Preprocessing with OpenCV
- Drawing on Images
- Affine and Non-Affine Transformation
- Building Histograms for Images
- Edge Detection and Blurring
- Read Videos
- Capturing Images with Web Camera
- Manipulating Videos with Previous Operations on Images
Introduction to Convolutional Neural Networks
- Introduction to CNN
- Why CNN Over MLP
- How Does Convolution Work on Images?
- How Does Color Image and Grayscale Image Work Over Convolutional Layers?
- Padding, Stride, Max Pooling Operations
- Convolution Arithmetic
Image Classification Case Study
- Image Classification on Handwritten Dataset
- Face Mask Detection
CNN Architecture
- Pretrained Model Introduction
- AlexNet, VGG16 and Inception
- ResNet and Skip Connections
Case Study with Transfer Learning
- Plant Diseases Prediction Using Transfer Learning
- CIFAR Using Transfer Learning
- Improving Face Mask Detection Model Using Transfer Learning
Object Detection
- Intro to Object Detection
- R-CNN
- Fast R-CNN
- Faster R-CNN
YOLO Algorithm
- Intro to YOLO Algorithm
- How YOLO Works?
- Introduction to Roboflow
YOLO Case Study
- Helmet Detection Using YOLO
Image Segmentation with Case Study
- Introduction to Image Segmentation
- A Case Study on Image Segmentation
Project on Computer Vision
- Understand image-based business problems and define computer vision objectives.
- Collect and preprocess image and video datasets.
- Perform image augmentation and normalization techniques.
- Build computer vision models using OpenCV, CNNs, and Transfer Learning.
- Develop applications such as Object Detection, Face Recognition, Image Classification, & Pose Estimation.
- Train and evaluate deep learning models using appropriate CV metrics.
- Optimize model performance for real-time inference.
- Integrate computer vision pipelines with live webcam and video streams.
- Deploy computer vision applications using Streamlit.
- Build end-to-end AI-powered vision systems for real-world applications.
Module 14: Projects and Final Assessment
Projects & Final Assessment
Projects & Case Studies
- Retail Sales Analysis
- Student Performance Management System
- PeopleOps Analytics
- Workforce Retention & Performance Analysis
- Retail Price Optimization
- ML Credit Risk Intelligence
- Automated Image Classification for Smart Logistics
- AI-Augmented Business Intelligence
- Build & Deploy an Enterprise AI Assistant

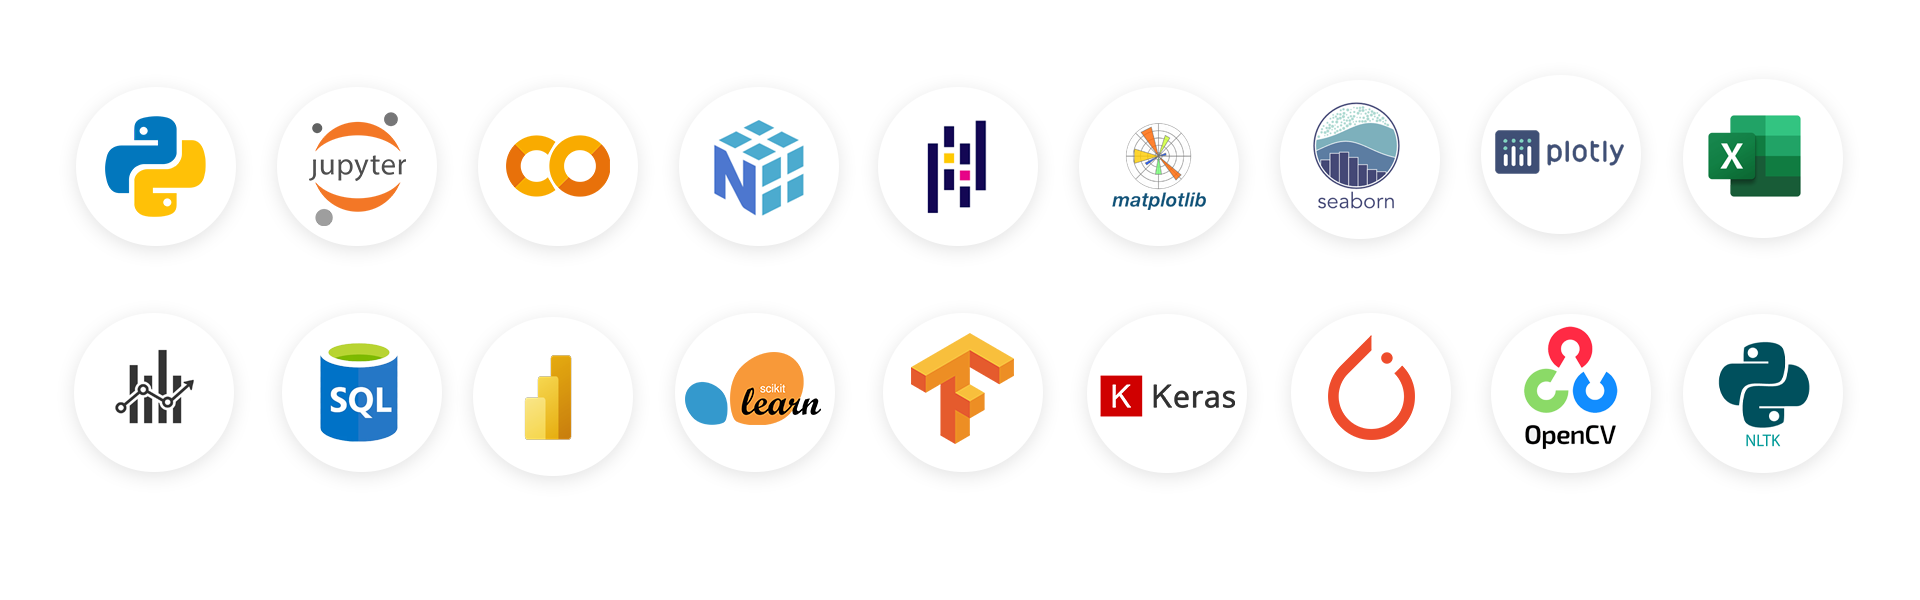
Languages & Tools Covered in Data Science course
Why Innomatics Stands Out the Best!
Why Data Science at Innomatics Research Labs?
- 500+ Industry experts from Fortune 500 companies
- Dedicated In-house data scientist team accessible round the clock
- 200+ Hours of intensive practical-oriented training
- Flexible Online and Classroom training sessions
- 5+ Parallel Data science batches running currently on both weekdays & weekends
- Backup Classes and Access to the Learning Management System (LMS)
- One-to-one mentorship and Free Technical Support
- FREE Data science internship on our projects & products
- Projects and use cases derived from businesses
- 30+ POCs and use cases to work, learn, and experiment
- Biweekly industry connections from industry experts from various sectors
- Opportunity to participate in Meet-ups, Hackathons, and Conferences
- Dedicated training programs for NON-IT professionals
- 100% Placement Assistance
- Globally Recognized Certification from NASSCOM FutureSkills Prime
What is the scope of Certified Data Scientists in India?
Data Science Continues to be One of the Most In-Demand Careers of The Digital Era
Data Science remains one of the most attractive and high-growth career options globally. With the rapid adoption of Artificial Intelligence, Machine Learning, Generative AI, and Big Data technologies, the demand for skilled Data Scientists continues to surge across industries.
According to recent industry reports, India is among the fastest-growing AI and data analytics markets in the world. Organizations across sectors such as IT, Healthcare, Finance, E-commerce, EdTech, and Manufacturing are heavily investing in data-driven decision-making, creating massive career opportunities for certified Data Science professionals.
Over the past few years, India has witnessed significant growth in AI adoption, with businesses increasingly leveraging data to enhance customer experience, optimize operations, and drive innovation. The integration of Generative AI and advanced analytics has further increased the demand for professionals who can extract meaningful insights from complex datasets.
The salary prospects for Data Scientists in India remain highly competitive. The average salary of a Data Scientist in major tech hubs like Hyderabad, Bangalore, and Pune ranges between ₹8–12 LPA. Entry-level Data Scientists typically earn between ₹6–10 LPA, while experienced professionals and AI specialists can earn ₹25 LPA or higher. In top-tier organizations and leadership roles, compensation packages can reach crores depending on expertise and domain specialization.
With continuous learning, hands-on project experience, and industry-recognized certifications, aspiring professionals can build a strong and future-proof career in Data Science. As organizations continue their digital transformation journey, the demand for skilled Data Scientists is expected to grow exponentially in the coming years.
Job opportunities (Careers) in Data Science Technology
Data Scientists are needed for businesses in every Industry. Even tech giants such as Google, Amazon, Apple, Facebook, Microsoft are constantly in need of Data Science experts who have in-depth knowledge in data extraction, data mining, visualization, and more. Here are some leading careers in Data Science
Business Intelligence Developer
With an average salary of $89,333, they design and develop business strategies for quick decision-making and growth.
Data Scientist
With an average salary of $139,480, they explore, analyze, visualize, and organize data for the companies. They analyze the complex data sets and processes to find patterns for decision making and predicting the business and drive strategies.
Applications Architect
With an average salary of around $134,520, they track applications behavior and applied in the business to analyze the way they interact with the user.
Industry Architect
With an average salary of $126,353, they analyze the business system and optimize accordingly to support the development of updated technologies and system requirements.
Enterprise Architect
With an average salary of $161,323 they work with stakeholders, including management and subject matter experts (SME), to develop a view of an organization’s strategy, information, processes, and IT assets.
Data Architect
With an average salary is $137,630, they build data solutions that can be applied on multiple platforms.
Data Analyst
With an average salary of $83,989, they transform and manipulate large sets of data, which incorporate web analytics tracking and testing.
Data Engineer
With an average salary of $151,498, they perform real-time processing on data that is visualized and stored.
Success Stories of Innomatics Alumni
Here are the Success Stories of our Innominions
Frequently Asked Questions (FAQs)
What will I learn in NASSCOM FutureSkills Prime certified Data Science?
In Data Science, you will learn how to find valuable data, analyze and apply mathematical skills to it to use in business for making great decisions, developing a product, forecasting, and building business strategies.
What is the average salary of a Data Scientist?
In India, Data Scientist salaries vary widely, typically ranging from ₹3 LPA to ₹20 LPA, depending on skills and experience. Here’s a quick breakdown:
Data Analyst: ₹3–7 LPA
Junior Data Scientist: ₹6–9 LPA
Data Scientist: ₹10–15 LPA
Are there any prerequisites to learn the Data Science course?
One need not have any major knowledge in Data Science. A basic understanding of technology is all enough to get started. It is better to possess knowledge of mathematical and communication skills, Python, R, and SAS tools.
What are my takeaways after completion of the Data Science course?
Based on the program you choose, you will get a course completion certificate from Innomatics, a Mastery-level certification from NASSCOM FutureSkills Prime, and for eligible learners a Professional Certification from TIH at IIT Bombay.
Is this course affiliated with IIT Bombay?
Yes. Alongside the NASSCOM FutureSkills Prime certification, eligible learners can also earn a Professional Certification from TIH at IIT Bombay, subject to the programme’s eligibility criteria and guidelines.
Does the course cover Generative AI and Agentic AI, or just traditional Data Science?
Yes. Beyond core Data Science, Python, and Machine Learning, the curriculum includes a dedicated module on Advanced Gen AI and Agentic AI covering LLMs, prompt engineering, LangChain, RAG pipelines, and AI agent development using real project work.
What are the career opportunities in Data Science Technology?
As data has become the never-ending part of this world, businesses need people to work with data for effective business processing. Organizations are ready to recruit and pay top dollars to the right dollars, which can leverage the business.
Here are some of the roles you can find in Data Science
Research Analyst
Data Scientist
Data Analyst
Big Data Analytics Specialist
Business Analyst Consultant / Manager
Data analyst
If I study a Data Science course in Hyderabad, is placement guaranteed?
Apart from the training, we do provide placement and career assistance with capstone projects and hands-on training after completing the course successfully. We do offer internship programs, mockup interviews, hackathons to gain more knowledge and explore a wide range of job opportunities.
Will I get any career support after the Data Science training?
All our trainees will have access to the Learning Management System (LMS), where they can get the backup classes and stay updates, 1-1 interviews, continuous updates on placements, and hackathons.
What is the eligibility criteria to learn a Data Science course?
Anyone who has a bachelor’s degree, a passion for data science, and little knowledge of it are eligibility criteria for the Data Science Course.